AxForge offering
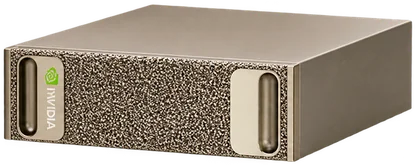
Subject to confirmed capacity and terms: A 128 GB GB10 Grace-Blackwell machine that is yours for the rental: full SSH access, your own containers and serving stack, hosted by AxForge in Málaga, Spain. Take the next available capacity or reserve a start time.
Check the console for current access, prices and availability.

Why AxForge
| 128 GB unified memory | Model weights and KV cache in one pool: dense models of roughly 7B to 35B, and far larger MoE models, on a single machine. |
|---|---|
| Full SSH access | Your environment, your containers, your serving stack. The machine is single-tenant for the whole rental. |
| European region | Hosted and operated by AxForge in Málaga, Spain (eu-es-1). Prompts on your machine are never persisted by AxForge. |
Specifications
| System | NVIDIA DGX Spark: dedicated, single-tenant |
|---|---|
| Superchip | NVIDIA GB10 Grace-Blackwell |
| Memory | 128 GB unified, shared CPU/GPU |
| CPU architecture | ARM64 |
| Access | Full SSH access |
| Rental term | Hour, week, month or year |
| Pricing | €1.19/hour on demand · €0.95/hour by the week · €0.91/hour by the month · €0.85/hour by the year |
| Region | Málaga, Spain (eu-es-1) |
| Trial | Trial access is available for qualifying customers. |
DGX Spark catalogue reference: specifications and requirements. List prices in EUR.
How it works
| 1 | Confirm capacity and terms in the console before the rental steps below. A public request records demand; it does not reserve or provision a machine. |
|---|---|
| 2 | Sign in to AxForge. |
| 3 | Choose your rental duration: hour, week, month or year. |
| 4 | Check availability or reserve a start time. |
| 5 | Add your SSH key. |
| 6 | Connect and deploy your models, containers and tools. |
| 7 | End the rental when your workload is complete. |
FAQ
Capacity and terms must be confirmed before a booking. Check the live availability in the console. Immediate and scheduled capacity are both supported.
€1.19/hour on demand, €0.95/hour by the week, €0.91/hour by the month or €0.85/hour by the year for a dedicated machine. Longer reservations earn the lower rate.
Dense models of roughly 7B to 35B, and MoE models far larger. Community benchmarks run 80B to 180B MoE models at usable speeds because only the active experts are read per token.
Most modern AI frameworks and container images ship ARM64 builds, and AxForge's own serving stack runs on it in production. x86-only binaries need ARM64 builds; an engineer can review your stack first.
No. Your model, your traffic, your dedicated machine. Prompts are never persisted by AxForge. Only operational metadata is kept for billing and operations.